Published: September 10, 2026
Last Updated: September 10, 2026
The terms “AI,” “machine learning,” and “deep learning” are even used almost interchangeably, and this just creates true confusion once you actually start figuring out where to begin learning. Related, but not the same. Which one you start with, that actually matters. Here’s the breakdown: what deep learning is, how it works, and where it sits inside artificial intelligence for beginners.
Short answer: deep learning runs on layered neural networks. Pulls patterns from raw data on its own. No manual defining what to look for, none of that.
Definition: Deep learning, a branch of machine learning. You don’t tell the model what features matter. It figures that out itself, running data through layer after layer, each one building on what the last one picked up.
What Is Deep Learning and How Does It Work?
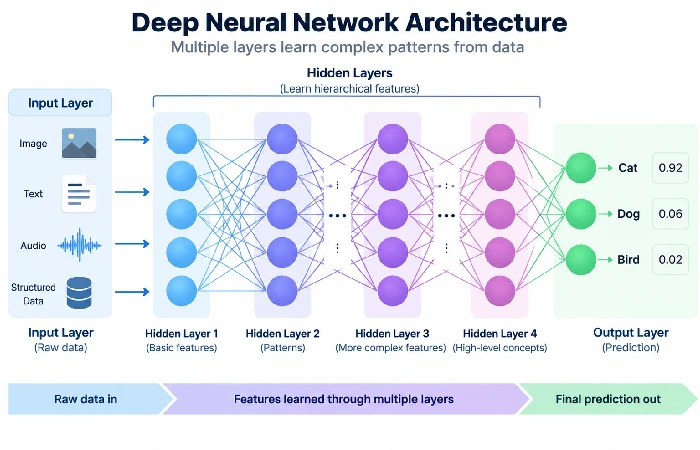
Deep learning is machine learning built on neural networks with at least four layers. That layer count is the actual dividing line between deep learning and a standard, shallower neural network, and IBM uses it as the working definition. It’s also what lets a deep learning model go from raw pixels straight to a finished prediction without anyone manually flagging which features matter.
Older neural networks needed a data scientist to hand-pick relevant features before training could even start. Deep networks skip that step. They figure out which features matter on their own, starting with broad patterns in the early layers and narrowing toward specific detail as the data moves deeper.
None of this would have been practical without hardware. Training a network with two or three layers was one thing; training one with dozens took GPUs capable of running the math in parallel, which is largely why deep learning didn’t take off until the 2010s despite the underlying theory being decades older.
This is also why deep learning is best understood as one technique inside a bigger field, not a separate thing sitting off to the side. If you want the wider picture first, the different types of artificial intelligence covers that ground.
How Do Artificial Neural Networks Work?
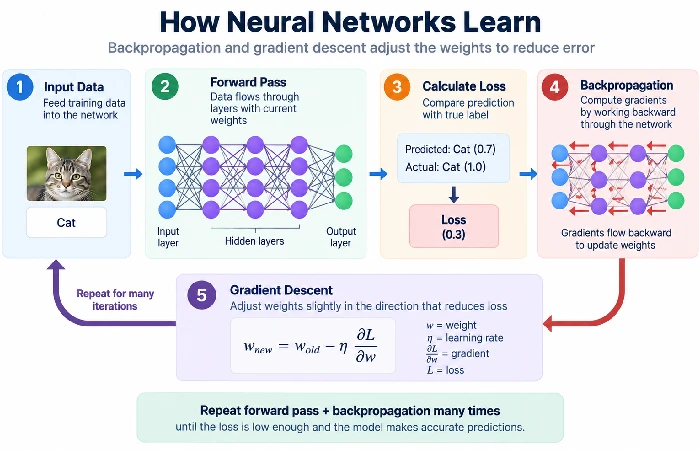
A neural network passes data through layers of connected nodes. Each node does a small math operation and hands the result to the next layer. Every connection carries a weight, and training is nothing more than adjusting those weights until the network’s predictions land closer to correct.
Two mechanisms do the adjusting:
- Backpropagation goes in reverse. Starts at the output, works back through each layer, and scores every weight on how much it drove the error up.
- Gradient descent takes those scores and shifts each weight just a bit. Always in whatever direction makes the error smaller.
When you hear that a large language model has 8 billion parameters, that is just 8 billion of these weights and biases working towards the same task. The training then repeats the backward and forward process many thousands or millions of times until the error is low enough to be useful.
Different Types of Deep Learning Models Explained
Deep learning models aren’t built one way. The architecture depends on what kind of data is going in, and four types cover most of what a beginner will actually encounter.
Convolutional neural networks scan images in small grid sections using filters, instead of wiring every single pixel to every neuron. That’s why they’re the default choice for image classification and object detection. Recurrent neural networks are different; in these networks, each step’s output is fed back in as the input for the next step. This means they maintain a certain ‘working memory’, making them suitable for speech-recognition and time-series tasks. However, they don’t perform well on long sequences.
Transformer models removed recurrence entirely in favor of a self-attention mechanism that allows the network to decide what parts of a sequence are relevant, rather than iterating through it. The design was published in a 2017 Google DeepMind paper and has largely replaced recurrent neural networks for the largest language models in production. Autoencoders perform the job of reducing the data into a condensed representation and re-expanding it. This enables it to denoise data, compress, and detect fraud without relying on labeled input.
If you want the generative side of this, GANs, diffusion models, image generation, generative AI explained goes into that separately.
Real-World Applications of Deep Learning
Deep learning’s already running behind the scenes in half the tools people use — most don’t even notice it. Virtual assistant understands your spoken command? That’s a deep neural network, crunching audio in real time.
All the rest just fall into a few simple groups. Computer vision is used to detect objects in self-driving cars and to identify possible cancer cells in diagnostics. Recommendation engines recommend the next thing a user might want from what they are already consuming. Machine translation and chatbots use natural language processing, who are also responsible for text summarization. Fraud detection systems use an autoencoder to catch suspicious transaction patterns as they happen.
None of this boils down to the end user having to understand a word about backpropagation. That gulf, between enjoying the deep learning tools and understanding them underneath, is what makes the field accessible to the absolute novice.
Deep Learning vs Machine Learning: What’s the Difference?
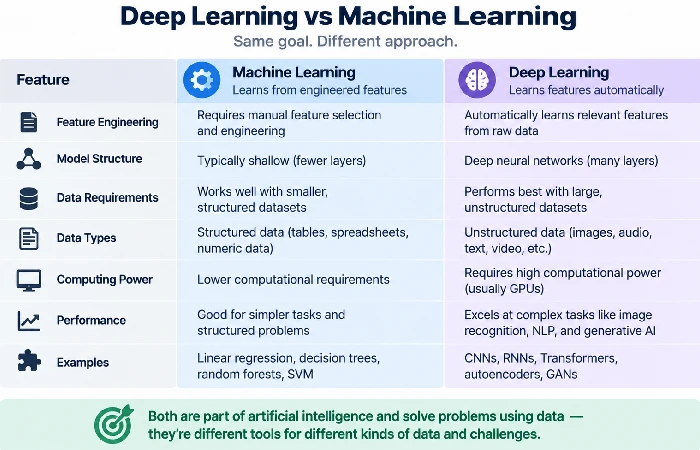
Deep learning isn’t an additional field it’s a subdivision of machine learning. The difference is about features. Most machine learning algorithms require a person to decide upon what features to use, and then engineer them before training. Deep learning bypasses this step and does that feature selection on its own.
You don’t have to learn classical machine learning to begin deep learning. This is a misconception, and it’s not true. These approaches solve some similar problems by using different methods (not sequentially on the complexity hierarchy). Machine learning is most effective on small, structured data (spreadsheets and tables, etc). Deep learning is most effective on large, unstructured data (images, sound files, free text, etc). The trade-off is that deep learning requires much more data and much more computing power.
They’re two different weapons in the same toolbox rather than a sequence. The first one you pick up depends on the type of data or problem you’re looking at – not which is more sophisticated.
Frequently Asked Questions
1. Is deep learning hard to learn for beginners?
It’s manageable if you already know basic Python, since the concepts build in layers much like the networks do. The math, linear algebra and the calculus behind gradient descent, is the harder part, not the coding. Plenty of people start building working models before they fully understand the math underneath them.
2. Do you need to learn machine learning before deep learning?
No. Deep learning’s a subset of machine learning, not some next level up. Basics help, training data, overfitting, that kind of thing, but it’s not a gate you have to pass through first. A lot of beginner roadmaps make it sound that way. It isn’t.
3. What are the types of deep learning models?
Four worth knowing, to start. Convolutional networks, for images. Recurrent networks, for sequences. Transformers, language and generative AI, the big one right now. Then autoencoders, compression and anomaly detection.
4. Can you do deep learning without a GPU?
Small models and tutorials will run fine on a CPU. Anything past that slows down fast. GPUs are what made deep learning practical at scale in the first place, so most people move to GPU access, local or cloud, once they’re training on real datasets instead of toy examples.